Your Microservices Are Talking Too Much And It's Slowing Everything Down | Savishty
Your application has been broken into microservices. Each service has a clear responsibility, teams can deploy independently, and your architecture looks scalable on paper.
But there's a problem.
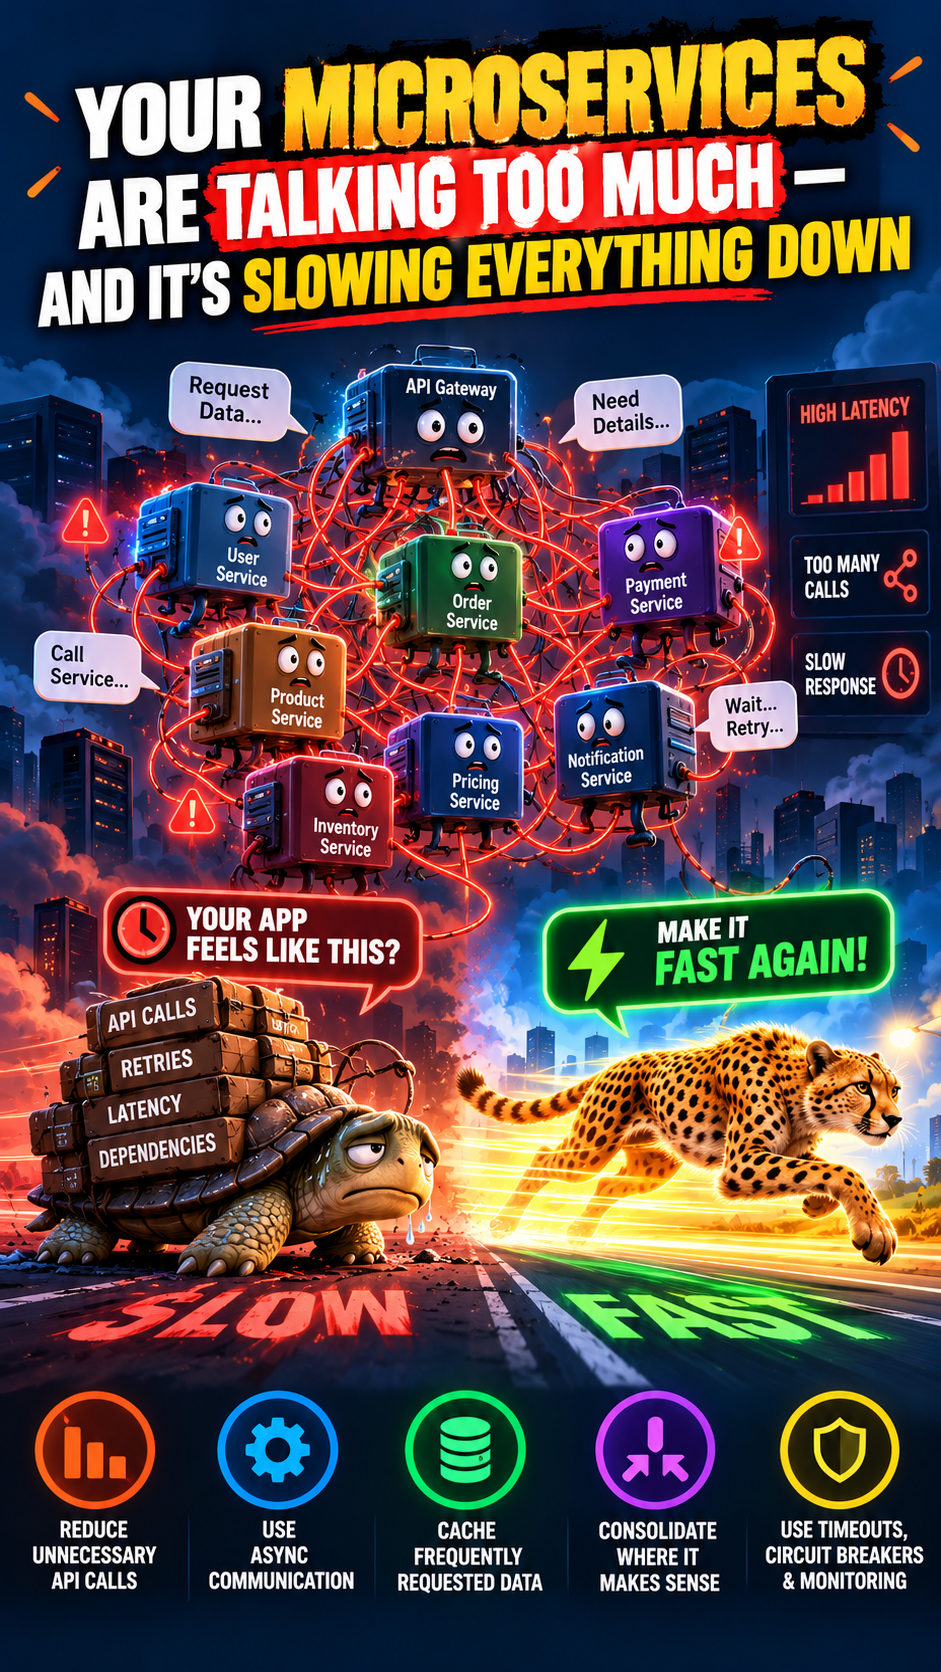
A single user request triggers dozens of internal API calls. Services wait for other services. Network latency keeps adding up. Retries multiply traffic. And suddenly, your supposedly scalable architecture is slower than the monolith you replaced.
The problem might not be your code. It might be how much your microservices are talking to each other.
Welcome to one of the most overlooked challenges in distributed systems: excessive service-to-service communication.
1. The Hidden Problem Behind Microservices

Microservices are designed to break large applications into smaller, independently deployable services. But every service boundary introduces potential communication overhead.
Imagine an e-commerce application where a customer opens the order history page.
The request might involve:
API Gateway
Authentication Service
User Service
Order Service
Product Service
Inventory Service
Pricing Service
Payment Service
If these services call one another synchronously, the original request may need to wait for multiple downstream operations before returning a response.
Each individual call might take only a few milliseconds. Across a long dependency chain, those milliseconds can add up.
And that's before accounting for network congestion, connection overhead, serialization, retries, or overloaded services.
The real danger isn't the number of microservices. It's the number of network calls required to complete one business operation.
2. How a Simple Request Becomes a Latency Nightmare

Consider this simplified request chain:
API → User Service → Order Service → Product Service → Inventory Service
Suppose each sequential step adds 40 milliseconds of latency.
Operation
Illustrative latency
API Gateway
20 ms
User Service
40 ms
Order Service
40 ms
Product Service
40 ms
Inventory Service
40 ms
Total
180 ms
These are illustrative numbers, not benchmark results. In a real system, network overhead, processing time, and dependencies may vary considerably.
Now imagine that the Product Service also calls Pricing, Reviews, Recommendations, and Promotions before returning a response.
The dependency graph grows. The request becomes harder to trace, and latency becomes harder to predict.
Why parallel calls aren't always the answer
Parallel execution can reduce latency when independent services can be called simultaneously. However, the overall request still waits for the slowest required dependency.
For example, if four independent calls take 20, 30, 40, and 100 milliseconds, the parallel portion takes approximately 100 milliseconds, excluding coordination overhead.
If all four calls are sequential, their combined duration could be approximately 190 milliseconds.
Parallelism helps, but it cannot eliminate slow dependencies or fix a fundamentally overcomplicated request path.
3. Five Signs Your Microservices Are Over-Communicating

1. Too many service dependencies
A single endpoint depends on multiple services that each call additional services. Changes become risky, and failures spread across dependency chains.

2. High p95 and p99 latency
Average response times look acceptable, but a meaningful share of users experience slow requests because some dependencies are occasionally much slower.

3. Excessive internal API traffic
Services spend substantial time making requests, waiting for responses, serializing data, and processing repeated calls.

4. Cascading failures and retry storms
A slow downstream service causes callers to time out and retry. Those retries create even more traffic, potentially worsening the original problem.

5. Difficult debugging
One user request spans many services, logs, and traces. Engineers struggle to identify where the time is actually being spent.
4. Why Excessive Service-to-Service Calls Hurt Performance
Network latency accumulates
A local function call and a network request are not equivalent. Network communication involves additional processing, transmission, and coordination.
Across multiple synchronous dependencies, this overhead becomes part of the user-facing response time.
Retries amplify the workload
Retries are useful for transient failures, but uncontrolled retries can create a feedback loop.
A service slows down, callers retry, traffic increases, and the overloaded service becomes even slower.
Use bounded retries, exponential backoff with jitter, sensible timeouts, and appropriate concurrency limits.
Data gets transferred repeatedly
If multiple services repeatedly request the same customer, product, or configuration data, your architecture may be moving information unnecessarily.
Sometimes the better solution is to return the required data in one response, cache appropriate data, or redesign service ownership.
Every dependency creates another failure point
Even if each dependency is individually reliable, a request that requires many dependencies has more opportunities to encounter a problem.
This is especially important when the dependencies are mandatory and execute sequentially.
5. How to Fix an Over-Communicating Microservices Architecture

The goal is not to eliminate communication altogether. It is to reduce unnecessary communication while preserving service boundaries, data ownership, and reliability.
Fix #1: Reduce Chatty API Calls
Instead of making multiple requests to retrieve closely related information, consider designing APIs around the needs of the consumer.
Before: The frontend calls separate endpoints for order details, product names, prices, and delivery status.
After: A purpose-built endpoint returns the information needed to render the order summary.
This reduces round trips and can simplify the client.
An API composition layer or Backend for Frontend (BFF) can help when different clients need different response shapes. However, avoid creating an aggregator that becomes another bottleneck.
Fix #2: Use Asynchronous Communication Where Appropriate
Not every operation needs an immediate response.
For example, after an order is placed, sending a confirmation email or updating an analytics pipeline usually doesn't need to block the customer's checkout response.
An event-driven design using services such as Amazon SQS, Amazon SNS, or Amazon EventBridge can decouple these operations.
Benefits include:
Reduced synchronous dependency chains.
Better isolation between services.
Independent processing and scaling.
Improved resilience when consumers temporarily become unavailable.
However, asynchronous processing introduces eventual consistency, duplicate-delivery considerations, and more complex debugging. Use it when the business workflow supports those trade-offs.
Fix #3: Cache Frequently Requested Data
If a service repeatedly requests relatively stable information, caching may reduce redundant calls.
Depending on your architecture, options include:
In-memory caching for suitable local data.
Amazon ElastiCache for shared caching.
Amazon CloudFront for appropriate cacheable HTTP responses.
Carefully designed application-level caches.
Set suitable expiration policies and understand invalidation requirements. Avoid caching data when doing so would violate freshness, authorization, or correctness requirements.
Fix #4: Consolidate Only Where It Makes Architectural Sense
Sometimes, two services communicate constantly because their responsibilities have been split too aggressively.
If two components always change together, share the same data transaction, and have no meaningful independent scaling or deployment requirements, reconsider whether they need to be separate services.
But don't merge services simply to reduce network calls. Independent ownership, security boundaries, fault isolation, and deployment needs still matter.
A well-designed monolith can outperform a poorly designed microservices architecture. And well-designed microservices can scale exceptionally well. The architecture must fit the problem.
Fix #5: Introduce Timeouts, Bulkheads, and Circuit Breakers
Performance optimization is also about preventing a slow dependency from consuming all available resources.
Timeouts prevent requests from waiting indefinitely.
Circuit breakers temporarily stop calls to unhealthy dependencies.
Bulkheads isolate resources so one failing dependency cannot exhaust the entire application.
Concurrency limits help control the amount of work a service accepts.
These mechanisms don't necessarily reduce the number of calls, but they can prevent communication problems from turning into widespread outages.
Fix #6: Use Distributed Tracing to Find the Real Bottleneck
Tools such as AWS X-Ray and OpenTelemetry help engineers follow a request across service boundaries.
Measure:
Number of downstream calls per request.
Time spent in each service and network span.
p50, p95, and p99 latency.
Error rates, timeouts, and retry counts.
Traffic volume and resource saturation.
Look for repeated calls, long sequential chains, and dependencies that consume a disproportionate amount of the request budget.
Optimize the measured bottleneck first—not the service that merely looks complicated.
6. A Practical Optimization Example
Imagine your checkout service makes eight synchronous calls to complete a request. Three calls are only needed for analytics and notifications; the remaining five are required for validating and processing the order.
A possible improvement is to move analytics and notifications into asynchronous workflows, reduce duplicate product lookups, and parallelize independent validation steps where safe.
The result could be fewer blocking operations and lower end-to-end latency.
But don't assume the improvement will always be dramatic. If the database query or payment provider is the actual bottleneck, reducing unrelated calls may have little effect.
Benchmark the original architecture, make one targeted change, and measure the result under comparable load.
7. The Architecture Question Every Engineering Team Should Ask
Before introducing another microservice, ask:
Does this service need independent deployment?
Does it have a clear business responsibility?
Will separating it introduce additional synchronous calls?
Can the consumer retrieve the data it needs efficiently?
What happens if this dependency becomes slow or unavailable?
Can the workflow tolerate asynchronous processing?
Microservices are a tool for managing complexity, not a goal in themselves.
The strongest architecture is not necessarily the one with the most services. It is the one that balances modularity, operational independence, resilience, and performance.
Final Thoughts
Your microservices architecture may be scalable, containerized, and deployed across a modern cloud platform—and still deliver a frustrating user experience.
Excessive service-to-service communication can increase latency, amplify failures, consume resources, and make troubleshooting harder.
The solution isn't to remove every service boundary. It's to remove unnecessary dependencies, avoid blocking work when it doesn't need to be blocking, cache appropriately, and measure the entire request path.
Fewer unnecessary calls. Smarter communication. Better performance.
That's how you make a distributed architecture work for your application instead of against it.
Did you find this helpful?